Brett BarkleyI am a Senior Research Scientist at Rivian, where I develop vision-language models (VLMs) and methods for long-tail detection in autonomous driving. I received my PhD from the University of Texas at Austin, where I was advised by David Fridovich-Keil and my research was generously supported by Google. Before that I was employed by the Johns Hopkins Applied Physics Laboratory, where I worked on AI-based autonomy for aerospace systems. I have an MS in Aerospace Engineering from the University of Maryland where I was a research assistant under Prof. Derek Paley and member of the Collective Dynamics and Control Laboratory (CDCL). My area of specialization was flight dynamics, stability, and control and my thesis proposed a scalable cooperative autonomy framework for multi-agent aerial reconnaissance. CV / Email / Google Scholar / LinkedIn |
|
News
|

|
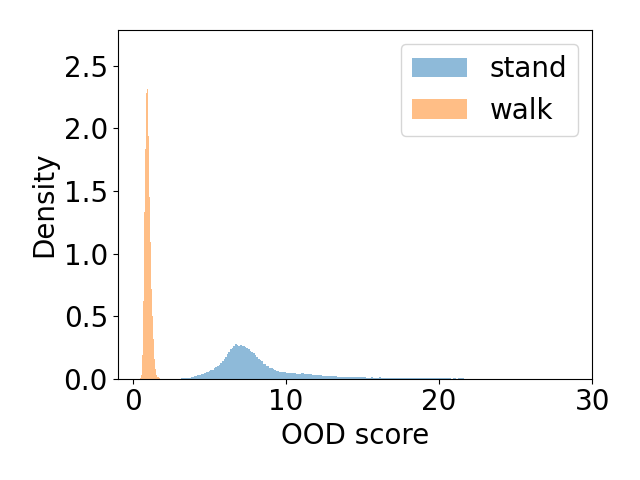
Scaling Pretrained Representations Enables Label-Free Out-of-Distribution Detection Without Fine-Tuning
Brett Barkley, Preston Culbertson, David Fridovich-Keil Preprint, 2026 arXiv We show that label-free OOD detection is increasingly a property of representation geometry rather than detector complexity. |
|
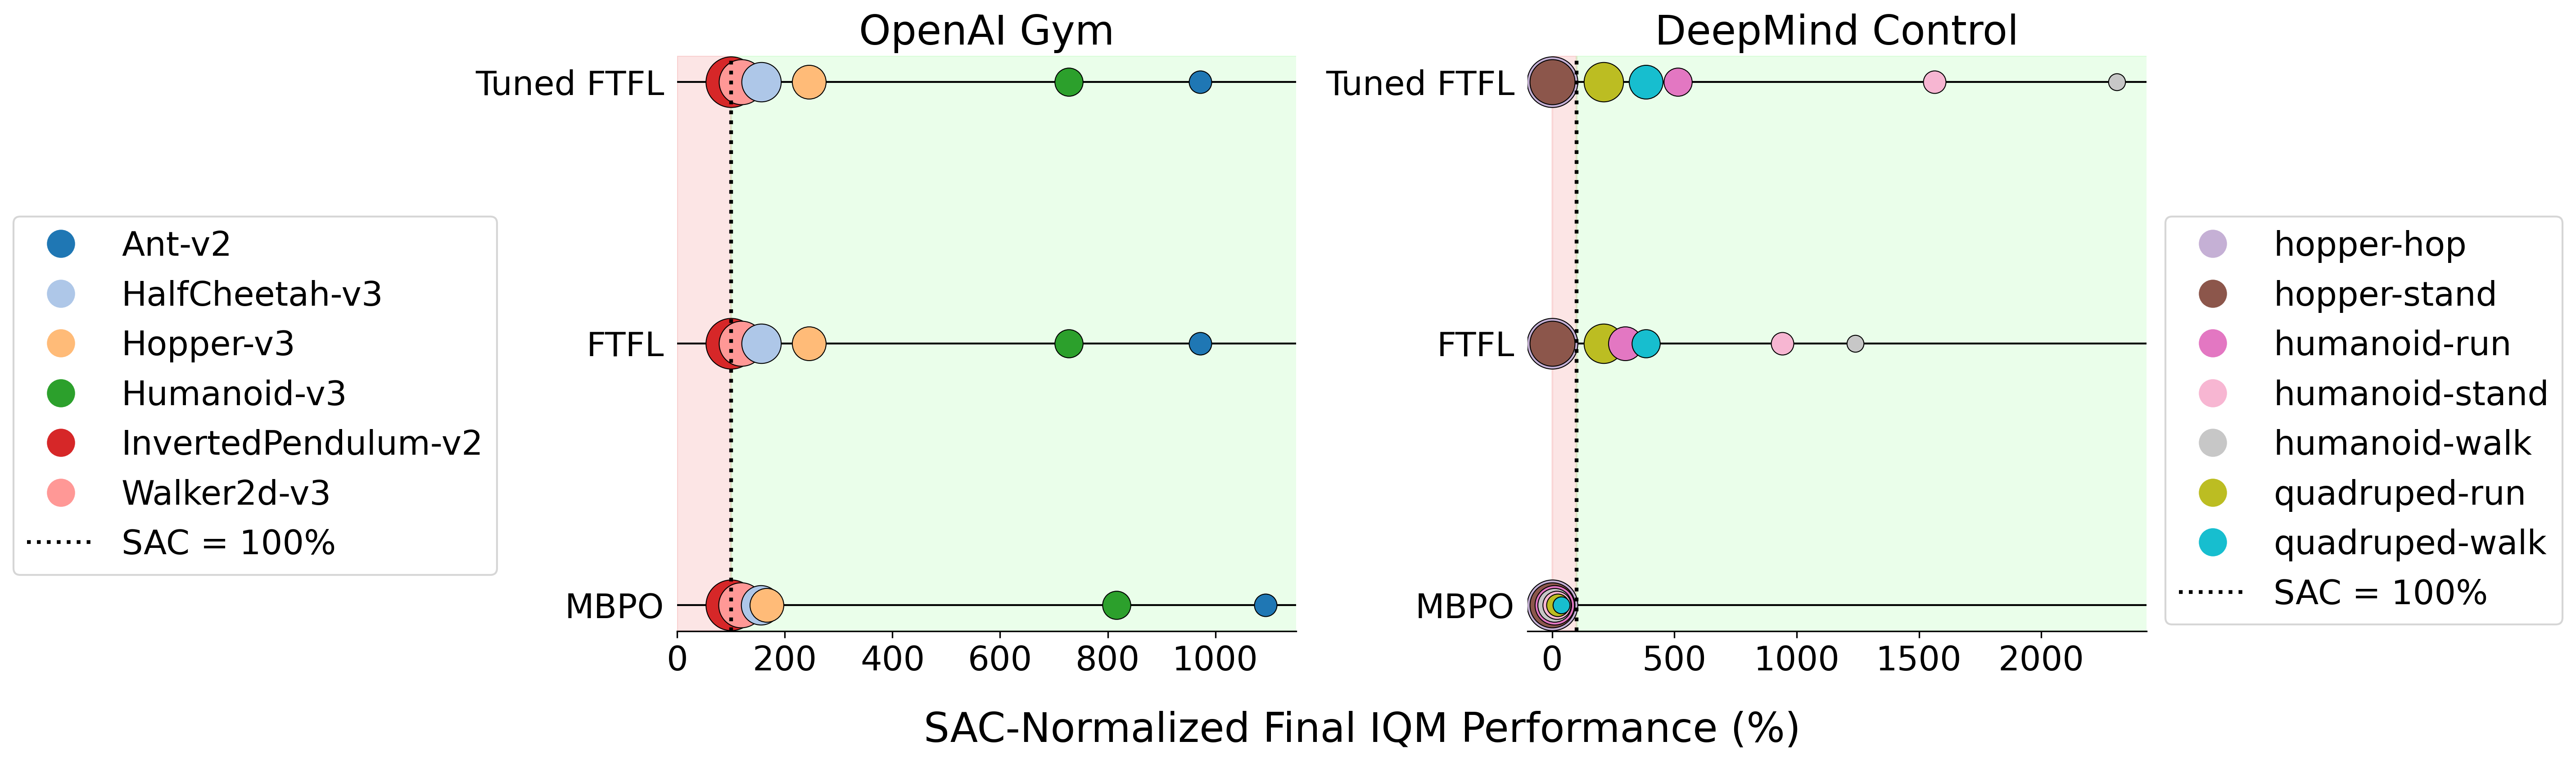
A Forensic Analysis of Synthetic Data in RL: Diagnosing and Solving Algorithmic Failures in Model-Based Policy Optimization
Brett Barkley, David Fridovich-Keil Preprint, 2025 arXiv We identify when, where, and why synthetic rollouts destabilize MBPO, and propose simple remediations that allow it to perform exceptionally well in environments where it previously could not improve beyond a random policy. |
|
SCOPED: Score–Curvature Out-of-Distribution Proximity Evaluator for Diffusion
Brett Barkley, Preston Culbertson, David Fridovich-Keil ICLR, 2026 arXiv We introduce a diffusion-based OOD detection method using score curvature to measure typicality, enabling fast, reliable detection across vision and RL datasets. |
|
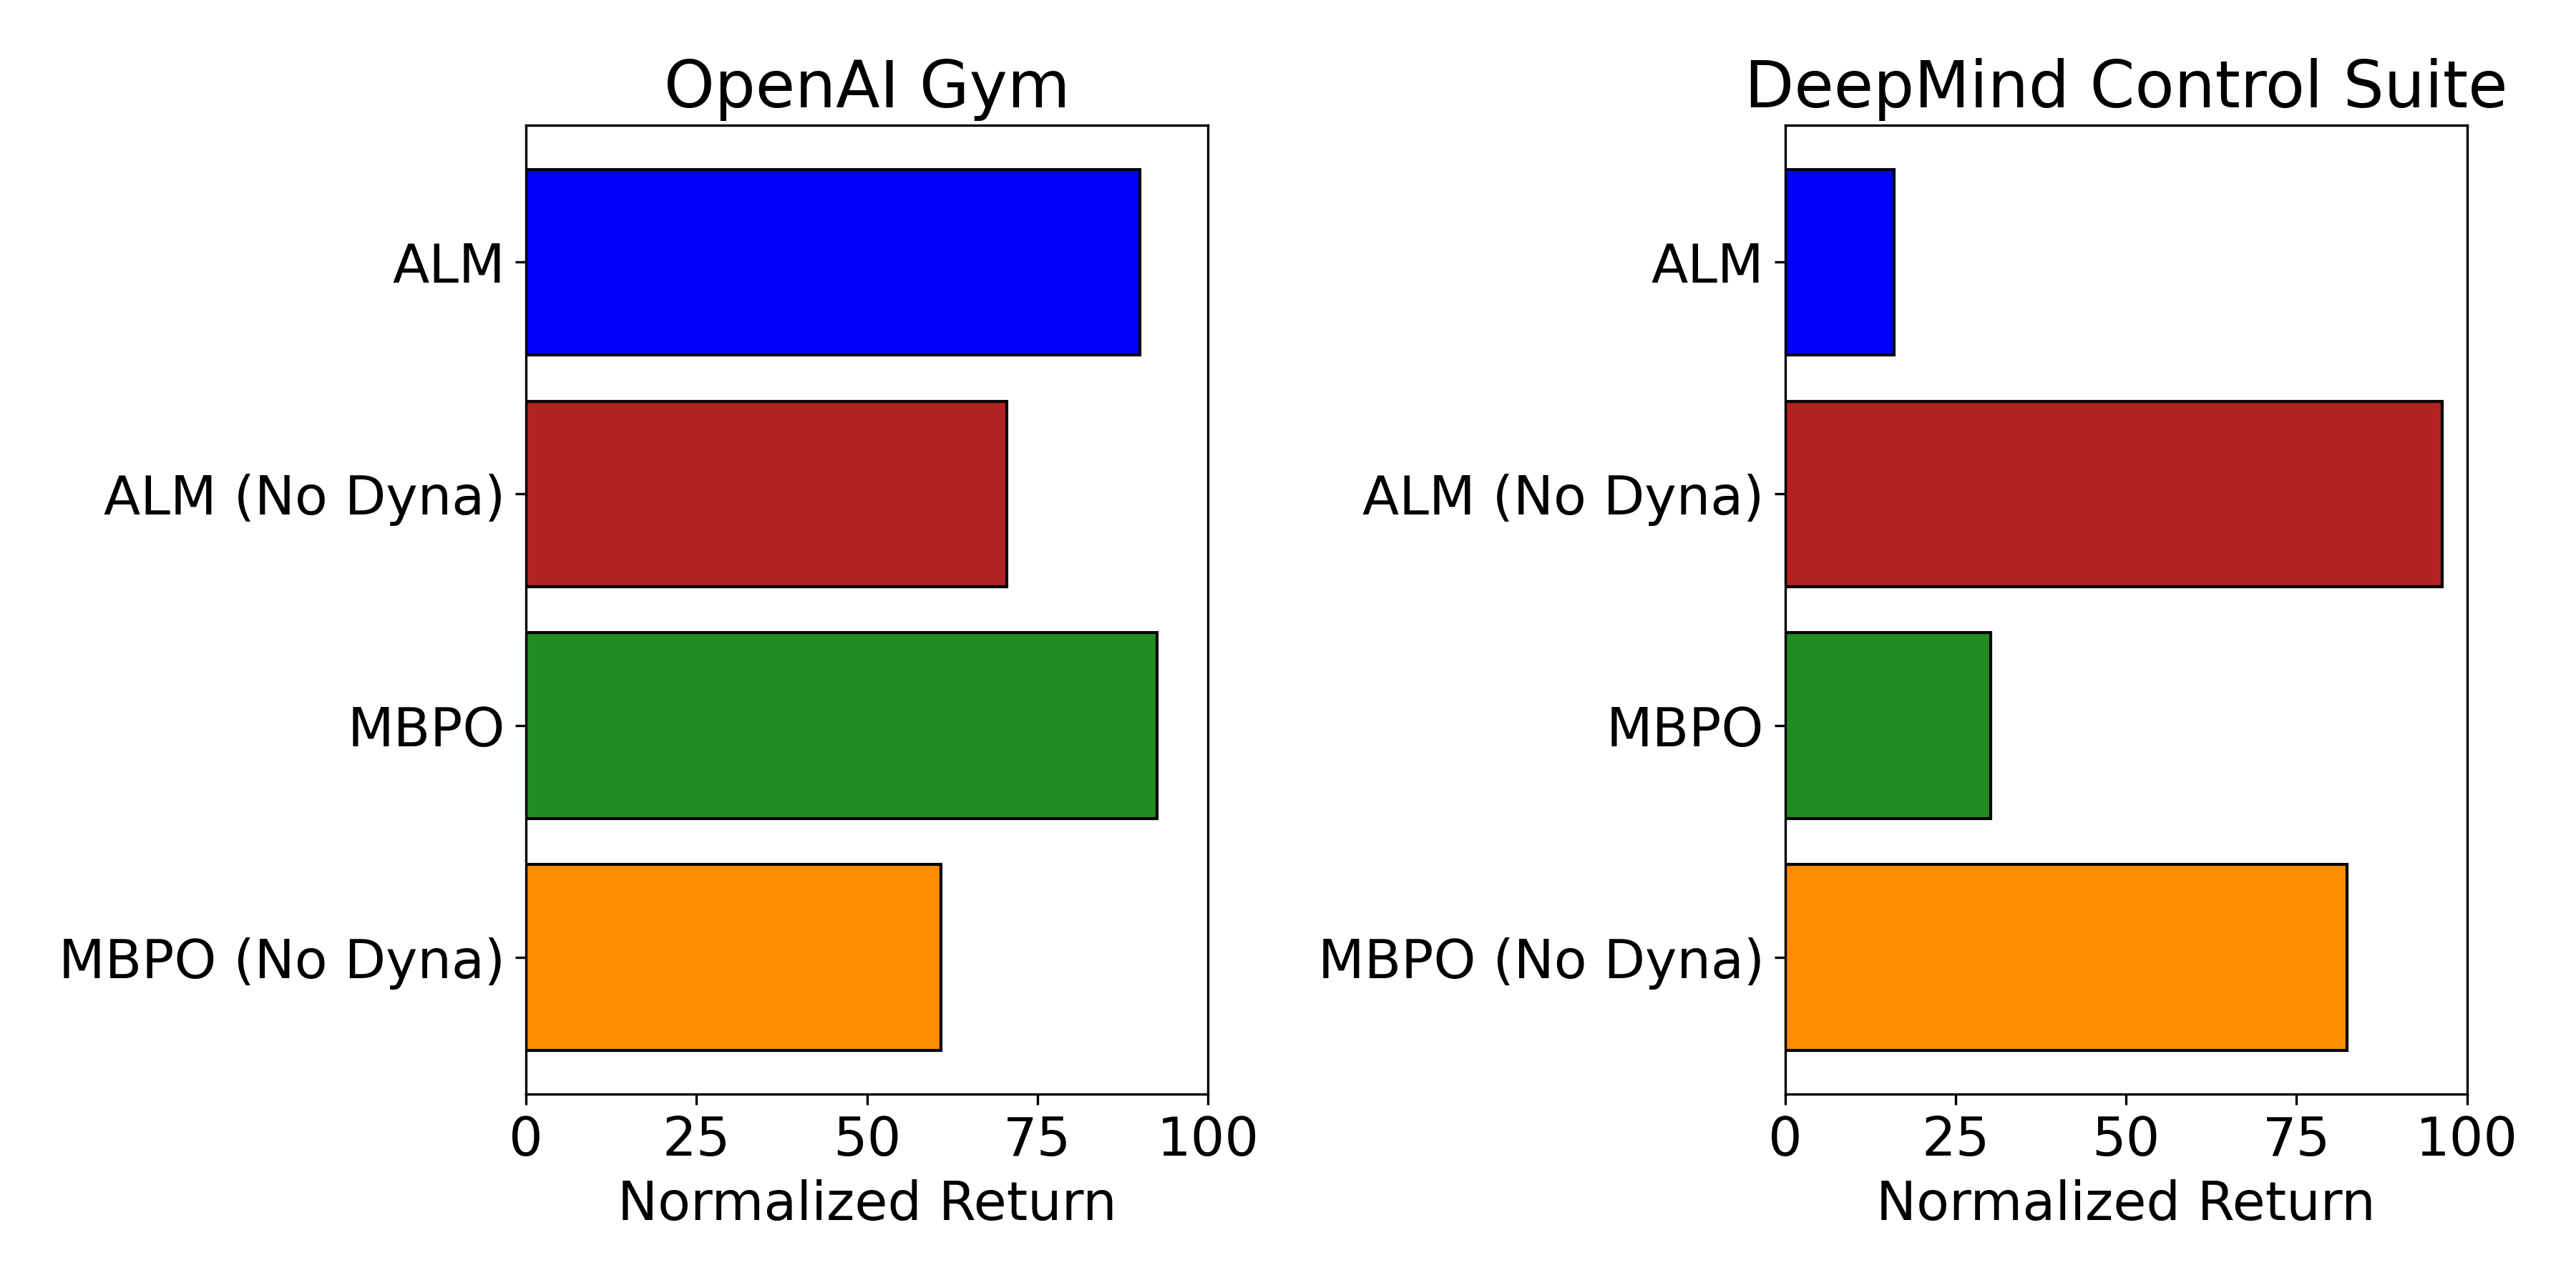
Stealing That Free Lunch: Exposing the Limits of Dyna-Style Reinforcement Learning
Brett Barkley, David Fridovich-Keil ICML, 2025 arXiv/ Code We show that synthetic rollouts in model-based RL can actually harm performance, identifying fundamental instabilities in Dyna-style methods. |
|
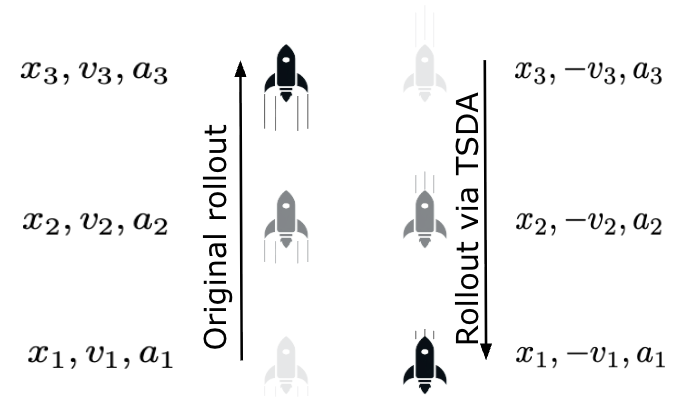
An Investigation of Time Reversal Symmetry in Reinforcement Learning
Brett Barkley, Amy Zhang, David Fridovich-Keil L4DC, 2024 arXiv We explore the role of time symmetry in RL algorithms and propose new augmentation strategies that exploit this structure. |
|
Design and source code adapted from here |